As the brute-force scaling of LLMs encounters economic realities, the primary AI moat is shifting from raw model intelligence to context and coordination layers. Discover why context is the new source code and how to build decoupled, resilient AI architectures.
Editor's Note: This post was written prior to the recent news regarding Oracle's force majeure declaration.
I have spent the last few months deeply immersed in agentic loops, local model inference, and building out the context ecosystem for The Foundry. This hands-on work has forced me to look less at individual model releases and more at the underlying economics of the AI industry. Looking at the board right now, I think we are approaching an inflection point.
I am not talking about a hard technological ceiling. I do not think anyone can credibly claim that LLMs simply will not get smarter from here. Rather, we are approaching something far more consequential: an economic plateau.
For the last few years, the dominant engineering strategy has been pure brute force: more data, larger parameter counts, and exponentially bigger GPU clusters. That strategy worked extraordinarily well, but the financial math of continuing it indefinitely is breaking down. High-quality human training data is finite, and training on synthetic data eventually hits diminishing returns. At a certain point, spending ten times more compute just to squeeze out a 2% bump on a coding benchmark simply does not make economic sense. Technical scaling may continue at the absolute fringe, but economic scaling is hitting a wall.
The Efficiency Counterargument (and the Token Price Collapse)
Let me steelman the counterargument: if frontier intelligence is experiencing diminishing returns, why does it feel like our developer tools are still getting vastly more capable every single month?
The genuine objection here is that models like Meta's open-weight Muse Glimmer 30B exist. While the flagship Muse Spark remains API-only, Glimmer has been sitting on Hugging Face under an Apache 2.0 licence since August. Taking near-frontier reasoning, which required a massive server rack in 2023, and compressing it into a 30-billion parameter model that I can run locally on an AMD Radeon RX 7900 XTX at over 100 tokens per second is a massive technical breakthrough. It is undeniable evidence of continued algorithmic and distillation gains.
However, those gains are happening primarily on the efficiency curve. They do not disprove the reality that gains at the absolute frontier are becoming prohibitively expensive. The floor is rising so rapidly that the delta between a multi-billion-dollar training run and a distilled open-weight model is vanishing. When everyone has an Einstein sitting locally on their laptop, the moat stops being Einstein himself. The moat becomes how effectively you manage his desk.
Look at the actual per-token price curve. Three years ago, flagship frontier models cost roughly $30 per million input tokens. Today, near-frontier reasoning, such as Muse Spark's contributor tier, runs at a mere $0.10 per million input tokens and $0.20 per million output. At a fixed capability level, that represents a 99% collapse in the price of machine intelligence in just 36 months.
When inference costs collapse to near zero, the entire system architecture changes. You stop trying to engineer the single perfect zero-shot prompt to save pennies. Instead, as I discussed when writing about how to cut AI costs with smart model routing, you can ask five specialized models at once. You can have one agent draft the code, another inspect it, another run unit tests, and another verify architectural guardrails, all executing in parallel within seconds for fractions of a cent.
The scarce resource is no longer raw intelligence. The scarce resource has become coordination and context.
From Models to Systems: The Four Layers of the AI War
This reality is driving the biggest architectural shift in modern software design. The first generation of AI engineering revolved around a simplistic, linear pipeline: User -> Model -> Answer.
The next generation of production engineering looks radically different:
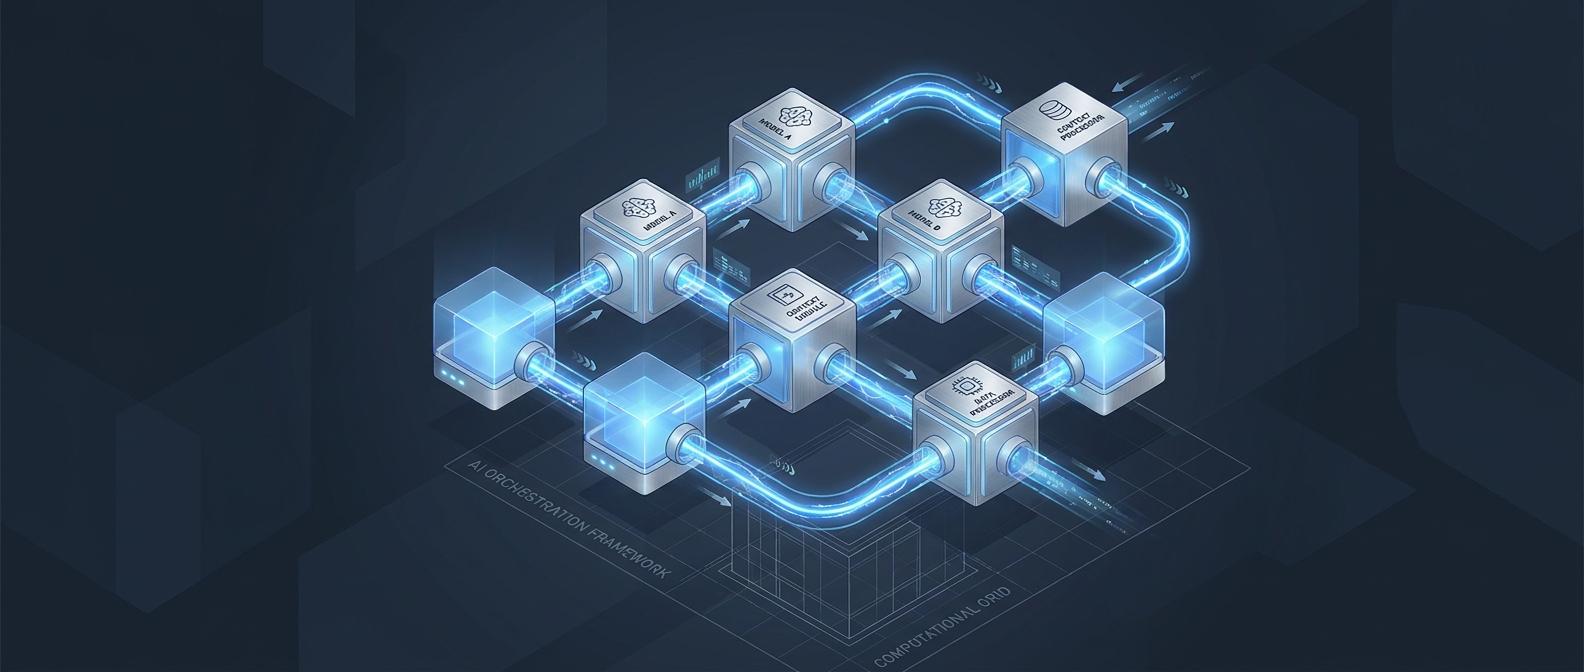
User -> Orchestrator -> Agents -> Tools -> Models -> Verification -> Result
In this architecture, models are becoming interchangeable dependencies inside a larger computational system, an idea we explored deeply in our work on my OpenSwarm system. The valuable engineering problems have moved upwards into routing, memory, context management, and governance. Because the major AI labs realise the pure model layer is commoditising, the tech giants are competing to control four distinct structural layers: Model, Compute, Context, and Workflow.
As the Model layer becomes harder to defend financially, durable commercial moats are migrating directly into Compute, Context, and Workflow.
1. Google: The Ecosystem Play
Google possesses the most obvious structural advantage: distribution. They are running the classic ecosystem playbook. Google's ultimate AI product isn't Gemini as a standalone web destination; it is Gemini becoming completely invisible. Your Drive, Docs, Gmail, Android, and GCP environment form the context engine. Eventually, the system holds so much institutional knowledge about your working environment that replacing it requires reconstructing your entire digital ecosystem. Google does not need the absolute smartest model on every benchmark. They just need one that is good enough that the friction of leaving keeps you locked in.
2. Anthropic & OpenAI: The Context Trap
Anthropic and OpenAI do not own an operating system or a desktop productivity suite, so their stickiness must come from the workflow layer. They want their agentic wrappers to become load-bearing pillars of your daily development environment.
Why is context so sticky? At its core, context is just text. The trap isn't the data itself; the trap is the lack of an export button. Providers take your repository histories, documentation, and user workflows, then chunk, vectorise, and structure them into proprietary, closed formats. You cannot simply click 'Export Knowledge Base' and drop it into a cheaper competitor. The friction of unspooling that context and rebuilding it from scratch is painful and expensive. You end up staying not because their underlying model is 3% smarter, but because removing it breaks your continuous integration pipeline.
3. Oracle: The Leveraged Infrastructure Gamble
Oracle is playing an aggressive hardware game. Having missed the initial cloud infrastructure boom, they are pivoting hard to position OCI as the backbone of AI compute. They pushed annual capital expenditure to a staggering $55.7 billion in FY2026 (more than 2.6 times the prior year's $21.2 billion), with forward guidance pointing to $70 billion net ($90 to $95 billion gross) in FY2027.
At first glance, their Remaining Performance Obligations (RPO) ending Q4 at $638 billion looks like an unassailable balance sheet fortress. Oracle points to roughly $75 billion in prepaid and customer-supplied hardware commitments, arguing this de-risks the capital they need to raise. However, their core vulnerability is acute counterparty concentration.
Roughly $300 billion of that $638 billion backlog is attributed to OpenAI contracts alone. If inference commoditises and unit economics tighten across the industry, stress at a single counterparty puts nearly half of Oracle's order book at immediate risk. Betting heavily on high-margin infrastructure returns while carrying $43 billion in debt and negative $23.7 billion in free cash flow is a massive operational risk if compute prices enter a structural race to the bottom.
4. Meta & SpaceXAI: Commoditise and Land-Grab
When you cannot defend pure model intelligence, you pivot to open infrastructure or developer user interfaces:
Meta: Meta's weapon of choice is open-weight commoditisation. By releasing Muse Glimmer under an Apache 2.0 licence, they use their ad-funded balance sheet to set fire to everyone else's API revenue moats. Releasing capable open weights actively crushes the unit economics of closed-model competitors. This strategy eventually positions Meta as a massive compute merchant: monetising infrastructure while driving the marginal cost of intelligence toward zero.
SpaceXAI (formerly xAI): Acquiring tools like Cursor represents an aggressive land-grab for the Workflow layer. If the model commoditises, the interface that routes developer intent becomes infinitely more valuable. Elon Musk will inevitably pitch orbital AI data centres as the future of computation, but their real immediate business will remain selling discounted, Earth-bound compute.
The Developer Takeaway: Context is the New Source Code
All of this creates a critical architecture challenge for software engineers. If we are not deliberate, we risk repeating the vendor lock-in mistakes of early cloud computing by building our applications around convenient proprietary context engines.
In modern agentic systems, your static prompts are not your core asset. Your context is. Your operational history, architectural decision records, and domain knowledge form a precise machine-readable representation of how your business operates.
Context is the new source code.
You must own it, version it, keep it stored in open formats, and inject it dynamically into models at runtime rather than letting a single model provider become its permanent host.
This architectural pattern is precisely why open standards like the Model Context Protocol (MCP) are vital for modern software design, as detailed in our guide on AI performance optimisation and efficiency. Open interfaces between models, local tools, and context stores directly neutralize vendor lock-in. MCP isn't the complete answer on its own, as we still require open protocols for portable memory, identity, and permissions, but it establishes a crucial principle: the model must consume your environment through an open standard rather than owning the environment itself.
If the economic plateau holds true, the defining question of software engineering won't be "Which model are you running?"
It will be: "Who owns the layer above it?"